Agentic RAG lets an AI application choose and repeat retrieval steps while preparing an answer. It can help when one search leaves important gaps. The extra reasoning also adds latency, cost and failure paths, so begin with a question that actually needs that flexibility.
Retrieval-augmented generation supplies a model with relevant information from external sources. In a fixed pipeline, the application decides the retrieval sequence. An agentic approach gives the model a bounded choice of search tools and a way to evaluate what information remains missing.
When agentic RAG is worth evaluating
A simple policy question may work well with one search and a grounded answer. A question comparing information from several systems may need multiple lookups. Choose the architecture from the work rather than adding a reasoning loop by default.
Microsoft’s agentic RAG architecture guide describes dynamic source selection, query decomposition and iterative refinement. These capabilities are useful candidates to test when the next search depends on the previous result.
For example, a question about affected products might first need a product list and then a lookup for each relevant advisory. A fixed retrieval pipeline remains a useful baseline. Compare the two against the same questions before choosing the more complex design.
Build agentic RAG around narrow search tools
Give each retrieval tool a clear purpose and predictable response format. A document search might accept a query and permitted date range. A record lookup might accept one validated identifier. Keep the caller’s access context outside fields the model can freely invent.
Also return source references, revision information and enough context to interpret a passage. A fragment without its effective date can produce a misleading comparison. Keep the link between the evidence and the final answer inspectable.
Next, define the stopping rules. Set limits for retrieval attempts, elapsed time and usage. Decide what the application returns when it reaches a limit without enough evidence. An explicit incomplete answer is more useful than an unsupported conclusion.
A worked agentic RAG question
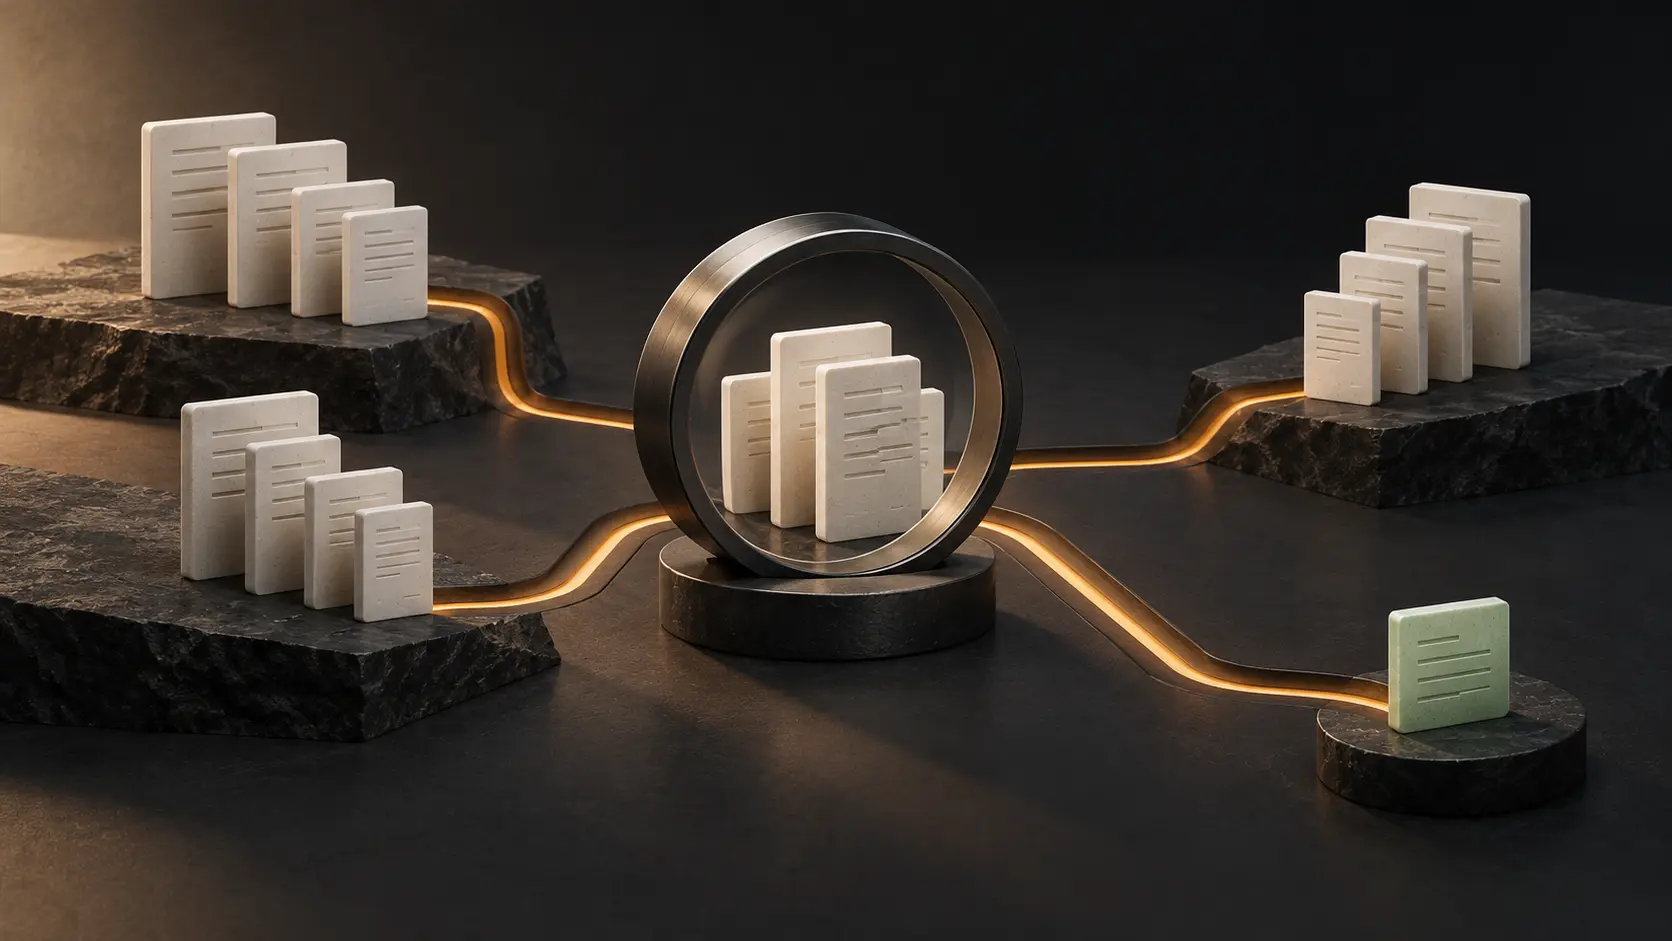
Imagine a hypothetical support analyst asking whether a service’s documented availability commitment differs between two regions. The relevant information lives in regional service documents with effective dates. The analyst has permission to read both.
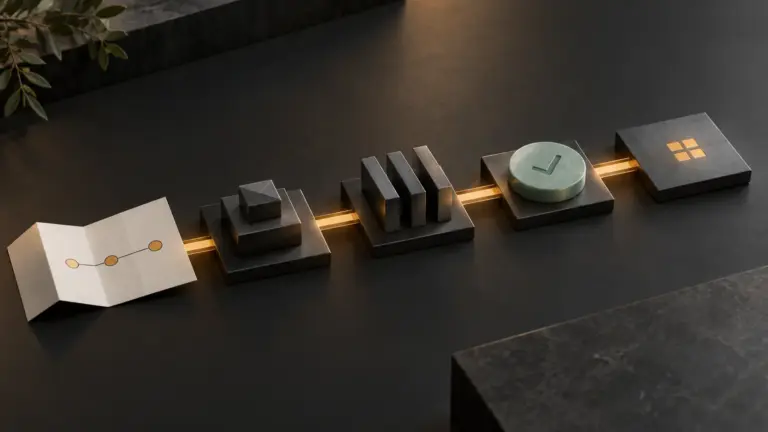
- Search for the first region’s current service document.
- Retrieve the second region’s corresponding document.
- Check the service, effective dates and scope of each commitment.
- Compare the supported values and explain any remaining uncertainty.
- Return source references for the claims in the answer.
The analyst’s question may sound simple, but the evidence can be mismatched. One document might describe a different service tier. Another might be an old revision. The application should identify these differences before presenting a numerical comparison.
If the second lookup fails, keep the first result and report the missing evidence. Do not replace the unknown commitment with a plausible value. This is a planning example; it does not claim a measured improvement from a deployed system.
Enforce access before returning evidence
Apply authorization in the retrieval service. A model choosing a tool does not establish permission to read its results. Test that an unrelated user cannot retrieve another team’s documents, even when a query includes an exact private title.
Treat retrieved text as evidence to inspect. A document may contain instructions aimed at the assistant. The OWASP prevention guide discusses indirect injection and layered controls. The application must preserve its original task and independently limit tool actions.
Keep retrieval and business updates distinct. A read-only research assistant may need no write capability at all. If a later workflow adds an update, define its authorization and review requirements separately.
Evaluate evidence quality and the final answer
Microsoft’s RAG design and evaluation series treats retrieval choices and evaluation as explicit design work. Build a test set with ordinary questions, ambiguous requests, missing sources and conflicting revisions.
First, check whether the application retrieved relevant permitted material. Then check whether the answer faithfully used it. A fluent answer with an irrelevant citation fails the second check, even if the search service returned useful passages.
Compare agentic RAG with the fixed pipeline on answer quality, unsupported claims, completed tasks, latency and cost. Also inspect the difficult cases individually. A higher average score can hide an access failure or a loop that never reaches a useful result.
Trace the loop without exposing private content
Connect each search, refinement and model call to the original task. Record why the application stopped and which sources supported the answer. Minimize captured content and test the fields that leave the application.
Our AI agent observability guide explains task-level tracing. Pair it with cost per accepted result so repeated searches remain visible in both the reliability and cost review.
Adopt agentic RAG from a demonstrated need
Begin with a fixed baseline and a question set that needs more than one lookup. Add bounded retrieval choices, enforce access and measure the outcome. Keep the simpler design when the added reasoning does not produce a useful improvement.
Make your information easier to use reliably
Tell Yasa which questions your team needs to answer, where the evidence lives and who may access it. We can discuss a retrieval pilot with clear acceptance criteria.