AI agent observability connects a user’s task to the model calls, tool actions and checks that produced its result. A useful trace should help an operator explain where time and cost went, why a step failed and whether the task actually reached an acceptable outcome.
Start with one workflow and a small set of operational questions. Then collect the evidence needed to answer them. This guide uses a hypothetical support-summary task to show how tracing, evaluation and data protection fit together.
Design AI agent observability around a task
Give the logical task an identifier and record when it starts, ends or remains unresolved. Keep retries and fallbacks connected to that task. Otherwise, a successful second attempt can hide the delay and cost of the first.
Represent the important operations as spans, with the relationships needed to reconstruct the workflow. Model calls, retrieval, tools and validation may each deserve a span. Also preserve context across queues or service boundaries where the task continues asynchronously.
The OpenTelemetry GenAI conventions project defines conventions for AI-related spans, metrics and events. Check the conventions supported by your instrumentation and pin compatible versions. Names and mappings need deliberate maintenance as the ecosystem evolves.
Give each operation enough context to explain it
For a model call, useful context can include provider, model, prompt version, duration, usage and finish reason where available. For a tool, record its name, target reference, duration and operational outcome. Keep the attributes tied to an actual troubleshooting purpose.
Also distinguish the requested action from the observed result. A model asking to update a record is different from a tool confirming the update. If the tool times out, the trace should preserve that uncertainty.
Use task identifiers in traces or suitable logs. Avoid turning every task identifier into a metric label: a new unique label value for every task creates an expensive, difficult-to-use metrics series. Keep aggregate dimensions bounded and useful.
A worked AI agent observability trace
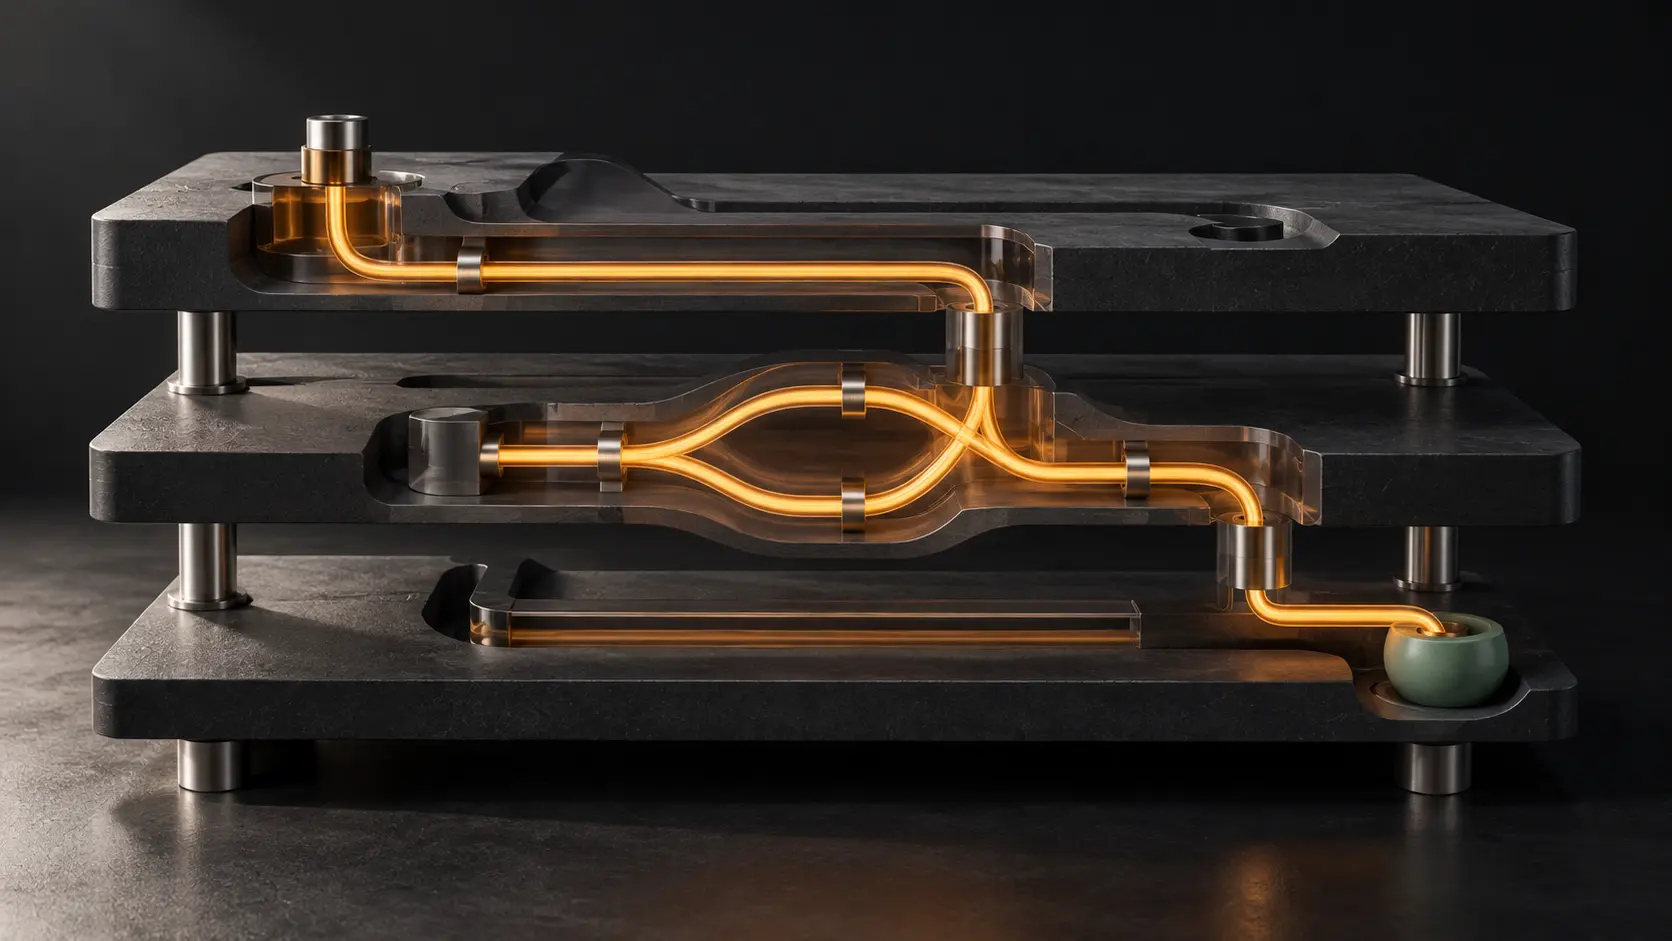
Consider an assistant preparing a support summary. It retrieves a case, asks a model what information is missing, looks up a policy and validates the final summary. The schematic below uses illustrative application labels, not literal OpenTelemetry SDK syntax:
support_summary [accepted]
  retrieve_case [ok]
  model_call_1 [ok]
  lookup_policy_1 [timeout]
  lookup_policy_2 [ok]
  model_call_2 [ok]
  validate_summary [pass]
The trace makes the retry visible. Next, inspect whether the first lookup consumed most of the task’s latency and whether the retry stayed within its budget. Also check that both model calls and both tool attempts contribute to the cost view.
Then connect the final validation result to its rule set or evaluation version. “Accepted” should have a defined meaning. A service returning a response does not establish that the summary preserved every important fact.
For asynchronous steps, preserve the relationship even when one continuous parent span is impractical. Your tracing system should still let an operator follow the task across the handoff.
Connect failures to the actual application state
Classify failures where they occur. A provider rate limit, a denied tool action, a malformed response and an application validation failure need different recovery. A single generic error count gives the operator little help choosing the next step.
Also plan for a timeout after a write. The downstream system may have committed the action before the response disappeared. Inspect the authoritative result before repeating an operation that could create a duplicate effect.
Test this behavior with fixtures. Simulate a tool failure, an expired credential, an output that fails validation and an uncertain write. Then verify that the trace contains the evidence an operator needs to distinguish them.
Protect data before exporting telemetry
Prompts, tool arguments and retrieved documents may contain private information. Decide which fields are necessary before enabling broad content capture. Use safe references or aggregate attributes where those can answer the operational question.
OpenTelemetry’s sensitive-data guidance recommends data minimization and reviewing what instrumentation emits. Its Collector guidance also describes processors for removing or transforming attributes. Apply those controls before data reaches a destination with broader access.
Also define retention, access and deletion procedures for the telemetry store. A redacted dashboard is insufficient if raw exports still contain credentials or document bodies. Test the exported payload with synthetic sensitive values, then verify that the unwanted fields are absent.
Combine AI agent observability with evaluation
Tracing explains execution. Evaluation assesses the result against the task’s requirements. Connect the two so a rejected output can lead back to the relevant retrieval, model and tool steps.
For example, a support summary might need to preserve the reported issue, distinguish confirmed facts from assumptions and identify the next action. Create representative cases with expected judgments. Then inspect disagreements rather than treating an automatic evaluator as an unquestionable answer.
Arize Phoenix is one example of a project combining OpenTelemetry-based tracing, evaluations, datasets and experiments. Evaluate a tool against your workflow, data controls and operating needs; the integration still needs acceptance checks of its own.
Measure the workflow users experience
Track completion latency, accepted-task rate, retries, tool failures and cost per accepted result. Also inspect slow and expensive tasks individually. Averages can hide an intermittent tool timeout or a loop that affects a small group of requests.
Choose sampling deliberately. You may need detailed evidence for failures while limiting routine capture. However, document what the sampling policy can miss, and keep the data-protection rules consistent across sampled and unsampled paths.
Finally, make alerts actionable. Include the affected workflow and a safe correlation reference, then link to the runbook. An alert that says only “agent error” leaves the investigation at its starting point.
Start with one task you can explain
A useful first implementation makes one workflow’s actions, uncertainty and final outcome visible. Check the failure cases, verify the exported fields and confirm that the team can use the evidence during an incident.
For application and workflow integration, explore Yasa’s development support. A single task trace and the question it cannot answer are useful starting material.
Make a difficult workflow easier to explain
Tell Yasa which agent task is hard to troubleshoot and what your current logs leave unclear. We can discuss a focused integration and the evidence your team needs.