AI coding agents can turn a development brief into changes across a codebase. Getting useful results takes more than a good prompt: the task needs clear boundaries, working tests and a reviewer who understands the outcome.
First, start with one contained problem. Give the agent enough context to investigate it, then judge the result against the original need. This guide explains how to build that workflow without handing over decisions your team still needs to own.
What AI coding agents actually do
A coding assistant may suggest the next line or explain a function. An agent can work through a sequence of steps: inspect files, propose a plan, edit code and run tools. However, its available actions depend on the product, environment and permissions you configure.
For example, an agent could trace a broken menu from its button to the event handler, change the handler and run the relevant checks. It may also prepare a pull request. However, producing a plausible change does not establish that the original problem is fixed.
GitHub’s application card for Copilot agents describes different execution environments and their limits. That distinction matters when evaluating tools: a local command-line agent and a hosted agent can have different access and review controls.
Choose the first task for AI coding agents
A useful pilot has an observable result and a manageable failure cost. A mobile navigation defect, a missing validation rule or an outdated integration test can provide a clear starting point. Therefore, pick work your team can assess independently.
Next, define what the agent may change. A request to repair one component should identify the component, its dependencies and the behavior to preserve. This reduces the chance of a small fix turning into an unrelated rewrite.
Keep the first assignment small enough to review in one sitting. For larger work, split it into useful stages with separate acceptance criteria. As a result, each stage should leave the application working and explain what remains.
Give AI coding agents a brief they can verify
A strong brief connects the reported problem to evidence. Include the affected route, reproduction steps, expected behavior and the checks that establish success. Also name any actions that require a separate decision, such as deploying the change.
The following example is a suggested brief for a mobile menu defect. Adapt the paths and checks to the actual project.
Outcome: The mobile menu opens and closes reliably.
Reproduce: At a narrow viewport, activate the menu twice.
Expected: The second activation closes the menu.
Scope: The existing navigation component and its relevant tests.
Preserve: Desktop navigation, visible labels and existing links.
Acceptance: Pointer and keyboard operation both work. Expanded state
matches visibility. Escape closes the menu and restores focus.
Delivery: Explain the cause, show the change and report checks run.
Boundary: Prepare the change for review; deployment is separate.
This gives the agent a concrete target. In addition, it gives the reviewer a way to challenge an incomplete answer. If the click behavior works but keyboard focus disappears, the task still needs attention.
Build a development loop that survives interruptions
Longer tasks need continuity. Keep setup instructions, relevant decisions and progress notes alongside the work. Record which checks passed, what changed and the next unresolved step. Then a fresh session should be able to inspect the current state and continue.
Anthropic’s work on long-running agent harnesses explores this continuity problem. Its approach uses environment setup and incremental progress records. The broader lesson is practical: a large context window does not replace a well-maintained working environment.
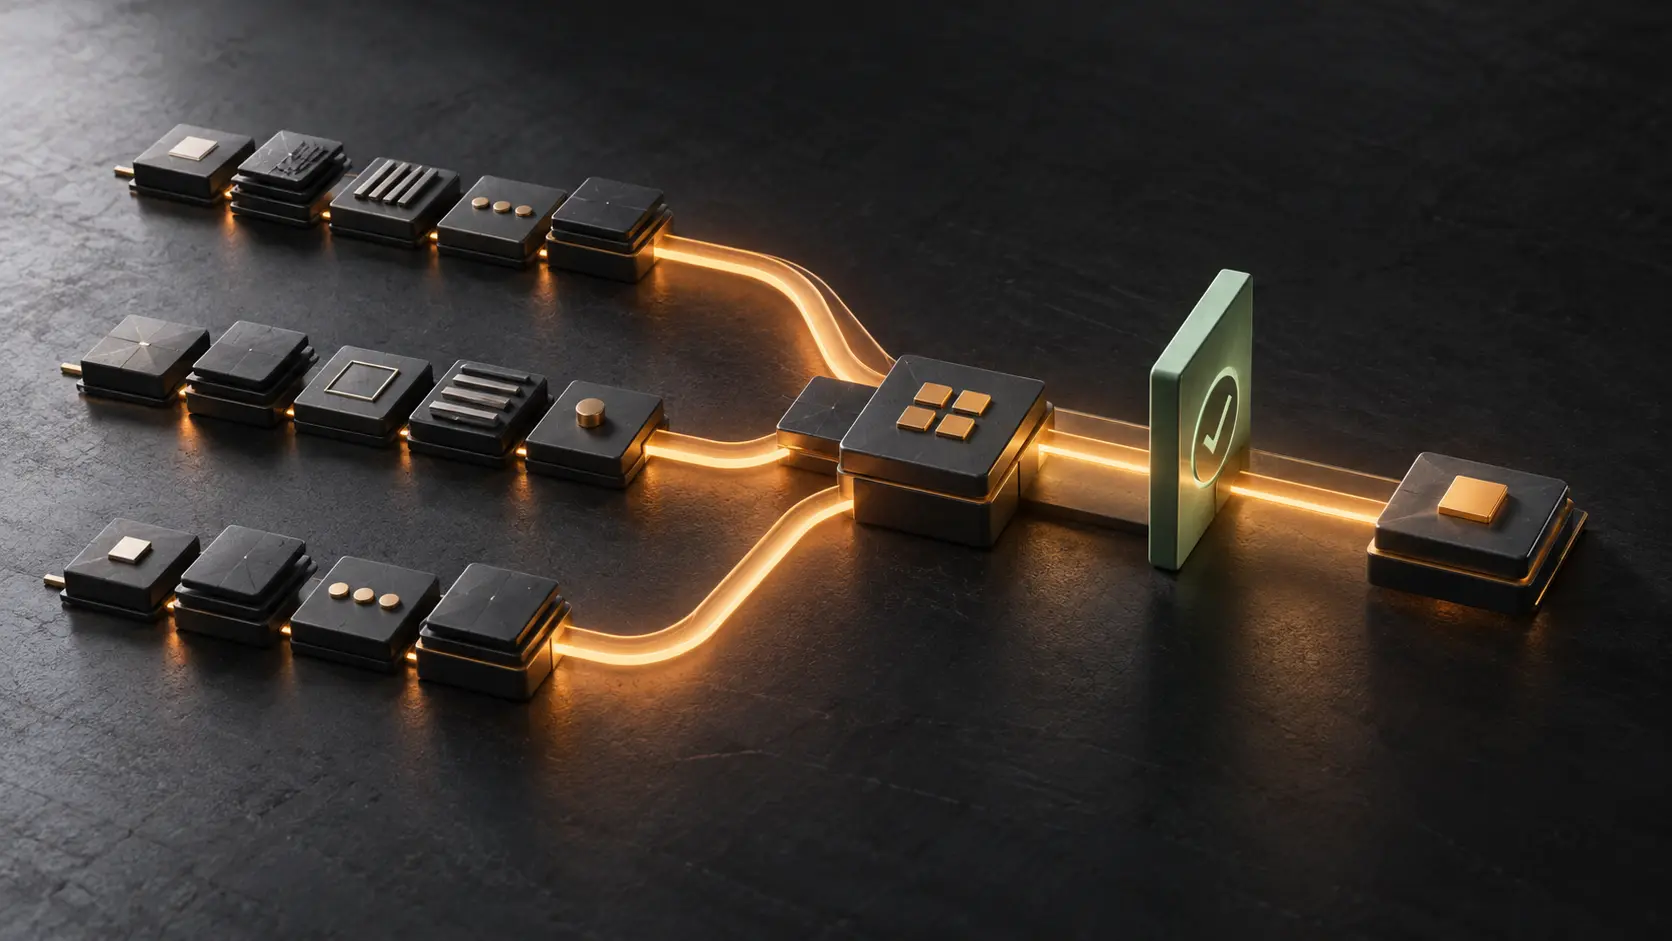
- Establish the baseline. Reproduce the problem and run the relevant existing checks.
- Make one coherent change. Keep the edit connected to the agreed outcome.
- Inspect the result. Review the diff and repeat the original reproduction steps.
- Leave a clear handoff. Save the work and distinguish finished requirements from remaining ones.
Keep access proportionate to the assignment
AI coding agents should receive the access their task requires. A component fix usually does not need production credentials or access to customer records. Use an isolated working environment and test data where possible.
Also review the information the agent reads. Repository files, issue comments and external documentation can contain misleading instructions. Treat those materials as evidence. They should not silently expand the task or authorize new actions.
The OWASP secure coding with AI guide discusses tool permissions, untrusted context and dependency risks. For a pilot, translate those concerns into a few concrete controls: scoped access, reviewed dependencies and an explicit deployment boundary.
Review evidence instead of accepting the summary
An agent’s explanation is a useful starting point for review. However, check the actual files and behavior too. A confident summary can overlook a changed permission check, a deleted assertion or a regression outside the main example.
For the menu task, inspect pointer use, keyboard use, focus movement and expanded state. Then check the preserved desktop behavior. A test that merely confirms the new handler exists would leave these requirements unproven.
Above all, keep responsibility visible. The person accepting the change should understand its purpose and have enough evidence to assess its consequences. Yasa’s article on human judgment in AI-assisted work explores that wider relationship.
Measure completed work, including the review cost
More generated code does not automatically mean more useful delivery. Measure the time needed to reach an accepted outcome, including investigation, review and corrections. Also track rework after acceptance.
- Delivery time: How long did the task take from assignment to acceptance?
- Review effort: How much time did a person spend checking and correcting the result?
- Quality: Did the change introduce regressions or require follow-up work?
- Operating cost: What did model usage, execution and supporting tools cost for the accepted task?
Compare similar tasks and record the limits of your sample. For example, a successful documentation edit tells you little about a complex data migration. As a result, the next pilot should expand only the capability you have actually evaluated.
Start with one repeatable workflow
The best starting point for AI coding agents is work with clear inputs, sensible access and a result someone can verify. Write the brief, establish the baseline and agree how the team will accept delivery. Then improve the workflow from the evidence it produces.
If your project needs practical implementation support, explore Yasa’s development and integration services. A defined task is enough to begin a useful conversation.
Plan your first agent pilot
Tell Yasa where your development workflow slows down. Together, we can define a focused pilot and a result your team can verify.